Repository navigation
RoPE loses precision for Llama / Gemma + Gemma logits.float() - #29285
Conversation


Llama - Force float32 since bfloat16 loses precision on long contexts
Fix RoPE and logits.float()

|
Forgot to add I'm not certain if this will break CUDAGraphs for faster inference - hopefully not |
 ArthurZucker
left a comment
ArthurZucker
left a comment
There was a problem hiding this comment.
I'll have to check the compile test and everything, but we usually hate these kind of changes 🫣 the bug is real, I'll see if I can find a good alternative as this is pretty much only for training! Great catch 🤗
|
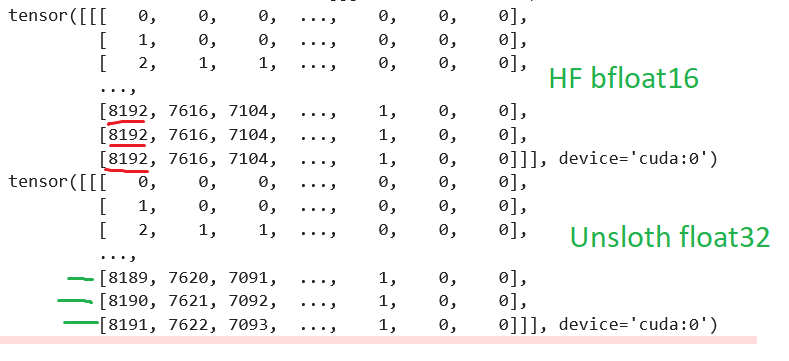
Sadly unsure if it's just for training :(( For inference I don't remember up to which context length, bfloat16 won't be an issue. I think it was up to 4096. However, bfloat16 loses precision even for inference sadly after 4096 context lengths. 8192 definitely - bfloat16 essentially thinks the last 4 tokens are all position 8192 ie [8192, 8192, 8192, 8192], whilst the correct float32 is [8188, 8189, 8190, 8191]. |

ArthurZucker
left a comment
ArthurZucker
left a comment
There was a problem hiding this comment.
LGTM let's do no grad and autocast, I'll test compile once you have both!

ArthurZucker
left a comment
ArthurZucker
left a comment
There was a problem hiding this comment.
LGTM, before merging I'll ping @pacman100, @younesbelkada and @fxmarty as this is pretty important! Feel free to comment if you are against these changes!
| self.base ** (torch.arange(0, self.dim, 2, dtype=torch.int64, device=x.device).float() / self.dim) | ||
| ) | ||
|
|
||

|
The docs for this PR live here. All of your documentation changes will be reflected on that endpoint. The docs are available until 30 days after the last update. |


|
@danielhanchen |

|
@gante Actually interesting point - I can see torch.autocast does arc sin and sinh etc in float32, but it doesnt list sin itself - I'll have to check if .sin() is done in float32 or float16 |
|
@ArthurZucker I checked everything and it's working! You guys can double check if anything is wrong. You can push the commit whenever. Thank you! :) |
ArthurZucker
left a comment
ArthurZucker
left a comment
There was a problem hiding this comment.
LGTM! Thanks a mile for this.
Let's make sure you run make style and make fixup for the last CIs

Co-authored-by: Arthur <48595927+ArthurZucker@users.noreply.github.com>
Co-authored-by: Arthur <48595927+ArthurZucker@users.noreply.github.com>
This reverts commit b860a22.


|
FYI -- as reported in pytorch/pytorch#128394, this change seems to break torch.export of the Llama 2 model. There seems to be two causes of the break:
Creating a model in
Wondering if there is a way to reenable export of Llama 2? Thanks! Cc: @angelayi @lessw2020 |
|
Hi @kwen2501 👋 Happy to iterate with you to get a working solution for I'm not experienced with with torch.autocast(device_type=device_type, enabled=False):
freqs = (inv_freq_expanded.float() @ position_ids_expanded.float()).transpose(1, 2)Isn't |


|
Hi @gante and @kwen2501 and @angelayi, (to your question, short summary is autocast will dynamically lower the precision to fp16 where it feels it can do so without losing precision. In this case it appears that for long context the lower precision could be negative and hence the reason to ensure the freqs calc is always done in fp32). To try and speed things up in resolving, I've made a PR that removes the device type calcs that were being fed to the disabled autocast and of course removed the autocast itself. When I tested this on Friday, removing the autocast did enable torch.export to function as expected so this should resolve this for us. But appreciate any feedback on the PR in case I have missed something! |
|
Note - PR is failing CI due to this - @gante, would you be able to help review this error? |
|
I'll comment here as well - the primary reason why the context manager was placed was because mixed precision training would cause |
|
Thanks @gante @lessw2020 @danielhanchen ! I wonder if the user can divide the autocast enabling region into two to skip this disabled region? Perhaps we can a note to the Longer term, maybe it would be worth adding a |
|
Thanks @danielhanchen for the insight to the reasoning behind the autocast w/ enabled = False, here (I suspected there was likely more to the story). I did want to add that we had the inverse of this situation with fsdp - for fsdp mixed precision, if you explicitly set a model dtype to something esp .bfloat16, and then pass to FSDP, we respect that. That behaviour however, then generated a big commotion from HF about why wouldn't we secretly auto override this for mixed precision and keep fp32 weights. (because we respect what the user has directed). |

do you mean for ROPE? |
|
"What I'm reading then is that we SHOULDN'T merge this PR until we confirm that pytorch doesn't change the type of an explicit .float() cast when autocast is active. Otherwise, we will get a regression (thank you @danielhanchen for confirming 🤗 )" |
|
Hi all - we have a much better solution now by making some changes to how PP does the model tracing via PT export and with that, it now handles the autocast issue directly so no changes needed here in the transformer code. Thanks @danielhanchen @gante @ArthurZucker @kwen2501 for the details and convo on this. |

|
Thanks for updating, great to know that overall this will be seamlessly fixed for everyone! 🤗 |

### Details:
- *Sin/Cos table generation must run in f32 otherwise it has accuracy
issue*
 -  Reference : huggingface/transformers#29285

### Tickets:
 - *CVS-146672*


Tagging @ArthurZucker :)
When I was implementing Gemma for Unsloth, I noticed when one uses bfloat16, the RoPE embeddings get autocast to bfloat16, when we require it to be in float32. This causes the positional encodings to lose precision dramatically especially for very large context lengths.
Below I pasted the image on how HF for now handles RoPE. You can see the loss in precision when using bfloat16. I manually autocasted it to float32 in Unsloth, and you can see the expected positional encodings.
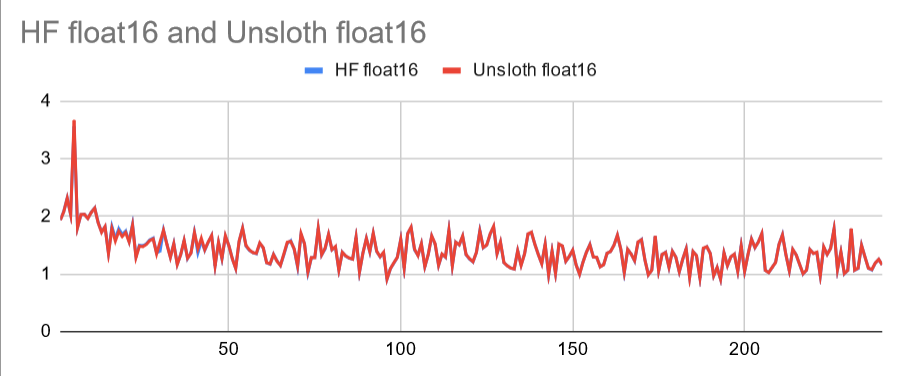
I couldn't find why Unsloth's error could not match that of HF's original Gemma implementation. On float16, this issue does not occur, with HF and Unsloth's training loss curve being equivalent:
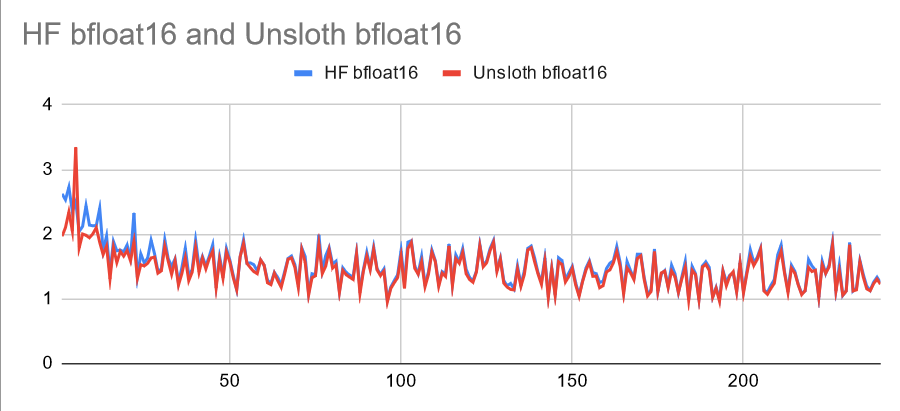
However when I switched over to bfloat16, HF and Unsloth's training losses diverge at the start, and Unsloth always retains a lower loss as training goes on:
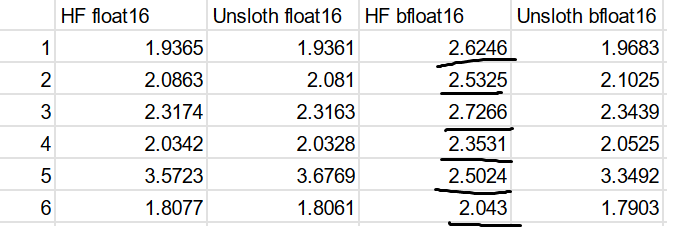
If you look at the losses more carefully (same seed), you can see the differences more closely.
The culprit I found was
where if one uses
torch.autocast(),freqs = (inv_freq_expanded @ position_ids_expanded).transpose(1, 2)gets done in bfloat16 and not float32. I propose we turn off autocast to force float32. Ie:This ensures
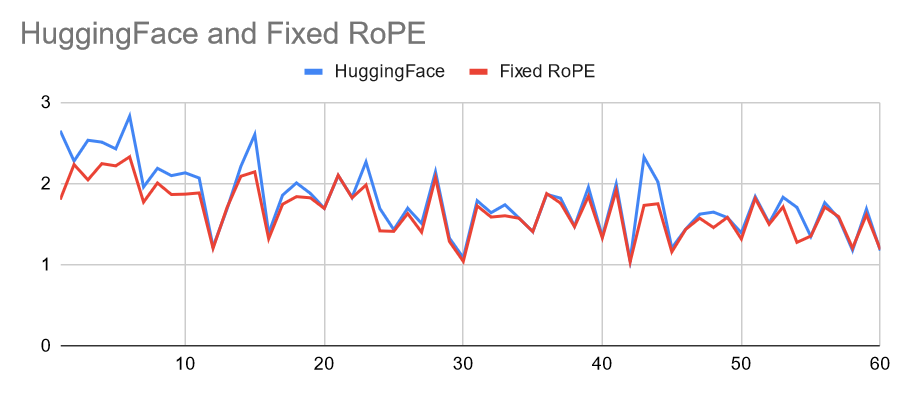
torch.autocastto turn off automatic downcasting to float16 / bfloat16 for the RoPE embeddings. My proposed fix shows the following loss curve:Also, in Gemma, a 1 liner was missed :)
logits = logits.float()must be placed to upcast thelogitsto float32. Although it should be done automatically intorch.autocast, it's best to keep the convention as done in llama, mistral and other models. Gemma's implementation seems to maybe have forgotten this 1 line :)