Repository navigation
[Status 03] InferRSI evolution: 48e0d589 → 68108700 (2026-10-31 catch-up) #286
Description

Delayed weekly catch-up for the reporting date 2026-10-30. Published on 2026-10-31 using the actual observation interval below; no intermediate daily observations are reconstructed. Historical editions and their comments remain unchanged.
1. Snapshot
- Previous edition: Status 02, #116.
- Observation interval: 2026-10-31 14:25–14:37 Asia/Shanghai, consolidating changes since the previous published body and its in-week updates.
- Published body baseline:
48e0d5894117be7c57f8b4ce793c0ec986f219e8. - Last published delta main:
7d1d82f55cda89842bd23ee2da91b521ee60eb08. - Pinned inspected main:
6810870046b4f493d39b6eaede0f1a4004369235, 113 commits ahead of the body baseline; full comparison. - Comment window: this issue's actual GitHub
created_atthroughcreated_at + 7 days, start inclusive/end exclusive, interpreted in Asia/Shanghai. The verified index receipt records the exact timestamps; the missed Friday slot is not the window's start. - Carried from in-week deltas: [Status 02] InferRSI evolution: ac702729 → 48e0d589 (2026-10-23) #116 comments 6431849624, 6437862891, 6472576809, 6495107891.
Developers now have accepted revision-bound PR feedback, complete-resource selection, local artifact evaluation and additional bounded workbench controls. The evidence includes regressions, neutral results and interrupted execution; these remain useful deliveries without establishing general skill effectiveness.
2. What changed
-
Knowledge can be selected and distributed as complete resources. feat: add opt-in skill selection and context to collect #129 adds opt-in relevance/context selection around the existing Reader; feat: add an installable Codex plugin preview #162 delivers a Codex-only local-executor plugin preview. Canonical inputs remain
src/inferrsi/data/skill_library/, with generated projections andtools/build_codex_plugin.py. #128 acceptance accepts software/evidence delivery, including 34 PASS / 2 INCONCLUSIVE attempts and 25.74% more input/output tokens for C than B; reduced cost with preserved quality was not accepted. The three-host [RFC] Agent plugins: a consistent InferRSI workflow in Codex, DSH and openJiuwen #152 goal is still open. -
PR evaluation progressed from planning to accepted real feedback. #101 accepts bounded real addition/update execution and trusted publication; #215 accepts cumulative-budget/advisory controls. Later historical runs retained a skill: add fixed-workload claim audit procedure #159 threshold-semantic regression and a neutral skill: clarify fixed-workload report aggregation #160 result. #235 accepts its diagnostic infrastructure/pilot with strict FAIL→FAIL; #246 accepts report-only component explanations showing improved diagnosis/next check while an extra citation still fails the aggregate.
tools/skill_eval_pr.py,skill_eval_auto.pyandskill_eval_feedback.pypreserve exact plans, obligations, uncovered scope and retained results. skill: add fixed-workload claim audit procedure #159/skill: clarify fixed-workload report aggregation #160 are now merged; earlier measurements are not revalidated at their final heads. knowledge: add bottleneck-driven mechanism decision cases #133 was closed without merge. -
Evaluation now retains executable artifacts, with narrower conclusions than a general agent benchmark. feat(skill-eval): add manual local artifact evaluation for #253 #258/fix(skill-eval): write frozen local inputs as UTF-8 bytes #261/feat(skilleval): add manual strict verifier qualification #266/feat(skilleval): bounded cloud generation and isolated artifact replay #267/feat(skilleval): fixed manual historical cloud generation job #269/feat(skilleval): explain artifact deltas and scoped next steps #271 add manual stage/capture, UTF-8/LF identity, isolated verification and itemized feedback. #253's corrected scope record retains the actual cloud generation/independent replay 19/19→19/19 tie on one public CPU parser fixture. It does not establish local iterative-agent equivalence or complete [Tracking] SkillEval evolution: local evidence, PR review and optional LLM judge #253. Separately, feat: qualify a bounded synthetic CPU KV reclamation task #274–feat: add inactive bounded KV pilot launcher #276 add a synthetic CPU KV reclamation task and bounded editing/qualification path. #281 records the first authorized run's interruption: one consumed A2 slot with unknown completion/usage, A3 not started, both grades INCONCLUSIVE. Consumed slots do not prove HTTP delivery or charges; the diagnostics repair cannot recover the earlier unknown cause and authorizes no retry.
-
Indexer delivery separates a limited speed improvement from unaccepted general accuracy. #255 remains open after its state correction. perf(indexer): avoid redundant view sizing after item limit #270 merges an exact-Bundle sizing fast path; its frozen 120-pair CPU study reports 9.434% lower primary latency, with a wide CLI-tail interval. feat(indexer): add opt-in raw-string substring ranking #272 adds explicit opt-in
weighted-raw-string-v1in_skill_selection.py, removing serialization-induced phantom matches while preserving defaults. Its 14 scalar cases/two ranking fixtures establish synthetic contract correctness. Earlier failed tail-latency, ranking and cue studies remain archived; neither these merges nor CI accept general retrieval accuracy or downstream agent benefit. -
Workbench extensions reuse existing execution and acceptance contracts. #137 acceptance covers deterministic offline goal checkpoints via
tools/goal_checkpoint.py; #147 re-acceptance covers the corrected offline Flare evidence adapter, not real Flare performance. fix: make run state and comparison verdicts match their evidence #202 strengthens terminal run states and evidence-bound verdicts under fix: run state and comparison verdicts can report support the artifacts do not establish #179. skills: extract backend-agnostic video diffusion optimization skeleton #207 extracts candidate backend-agnostic video-diffusion methodology; recent HF/SGLang GDN, Metal and serving-system source contracts broaden knowledge without qualifying devices or importing downstream engine runtimes.
3. Architecture delta
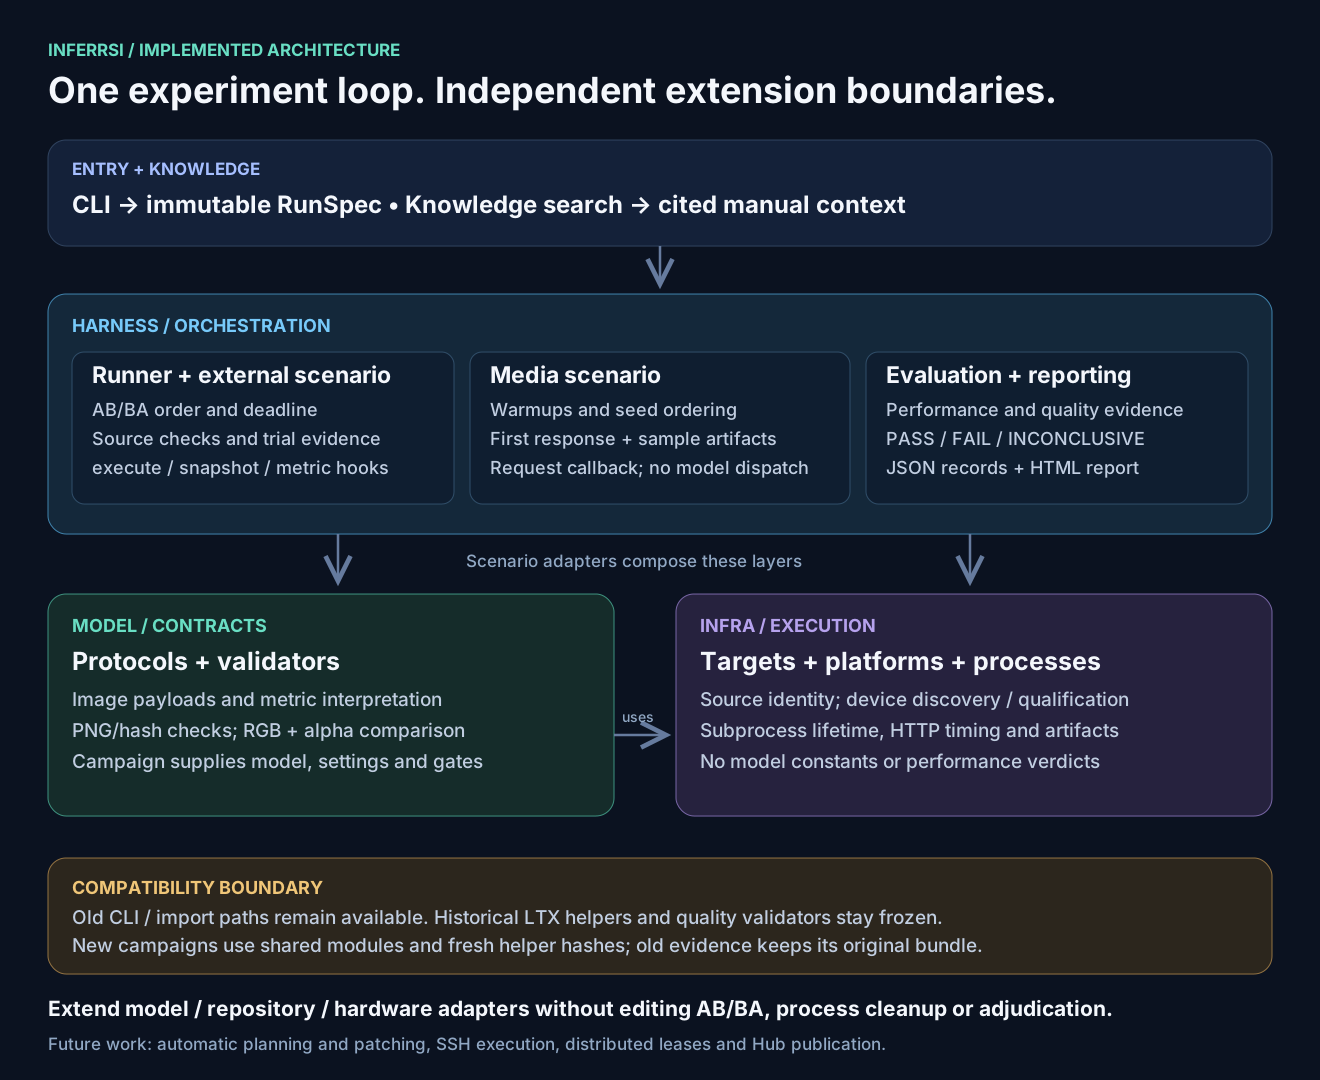
The maintained architecture retains Entry/Knowledge → Harness → Model/Infra. New concrete consumers include tools/skill_eval_local.py → harness/skill_eval_engineering.py, and model/anthropic_edit_agent.py / harness/kv_reclamation.py around existing isolated execution. Artifact qualification, actual provider execution and final effect remain separate. Reference/SearchSpace keep their original authority; no new status database or automatic promotion is introduced.
The generic diagram's future-planning line concerns the engine/campaign lane; PR planning and the bounded editing path above already exist. An independent semantic LLM judge and broad autonomous optimization remain proposed.
Documentation drift: daily-admission rollout wording still calls the checked-in configuration unchanged schema 1, while the inspected configuration is schema 2. Historical deployment settings and earlier proposed diagrams must be read with their dated scope and newer focused contracts.
4. Capability status and in-flight work
| Workstream | Code delivery | Goal acceptance / evidence | Existing ownership |
|---|---|---|---|
| #128, #137, #147; #101/#215/#235/#246 | Merged scoped implementations | Accepted only at the specific linked records above; negative/neutral outcomes preserved | Existing owners/acceptance records; Dong1017 is assigned to #128/#101/#215 |
| #253 / #248 | Artifact and bounded CPU editing paths merged | Trackers open; parser tie and KV interruption do not prove general effect | No assignees; Dong1017 coordinates the published slices |
| #255 | #270/#272 merged; failed candidates archived | General accuracy unaccepted; limited frozen performance scope only | No assignee; reuse existing coordination |
| #152 / #238 | Codex preview delivered / release-bot #239 still open | Other host acceptance / release operation remain unfinished | zengchuang-hw authored the Codex slice; broader owners not established here |
| #249 / #268; #91 | Parallel-round coordinator remains an open PR; knowledge work continues | Proposed integration and per-source coverage retain separate acceptance | NumberWan is assigned to #249; reuse existing #91 claims |
5. Evidence and limitations
This report used pinned source inspection, actual merge flags, issue bodies, specific acceptance records and retained owner/reviewer reports. The SVG was rendered locally before publication. It did not run tests, independently regrade artifacts, invoke evaluation/model clients, use GPUs, dispatch workflows or change repository settings.
Historical software checks, CPU measurements, provider results and independent acceptance are different evidence classes. Every measurement above retains its original revision/task/environment; none is a new measurement of 68108700. Preserved failures and INCONCLUSIVE outcomes are not invitations to rerun. Reservations are conservative obligations, not verified invoices. Public artifact availability/retention and external model identity remain limits.
6. Next decisions
- Under [Tracking] SkillEval evolution: local evidence, PR review and optional LLM judge #253/task: measure whether InferRSI helps Claude Code and Codex optimize inference tasks #248, dispose remaining acceptance criteria and the interrupted KV evidence through existing owners. Any new paid attempt needs separate valid authority; this report grants none.
- Under [Tracking] Skill Indexer: retrieval efficiency and accuracy #255, decide the remaining accuracy objective or explicitly adjust scope while retaining failed studies. Do not close the two-objective tracker because a performance slice merged.
- Complete [RFC] Agent plugins: a consistent InferRSI workflow in Codex, DSH and openJiuwen #152's host-specific acceptance, task: configure a GitHub Actions release bot #238's release delivery and task: parallel optimization rounds with orthogonal lanes for multi-agent harnesses #249's existing review within their own scopes. For [Tracking] SearchSpace distillation coverage and knowledge consolidation #91, continue existing claims and preserve source-versus-effect distinctions.
Activity
Dong1017 commentedon Nov 1, 2026
In-week developer update — 2026-11-01
1. Snapshot
Observed catch-up: 2026-10-31 14:40:09 → 2026-11-01 19:12:14 Asia/Shanghai, from the edition's actual publication to this consolidated check. This does not reconstruct intermediate daily observations; the weekly body remains unchanged.
6810870046b4f493d39b6eaede0f1a4004369235.67ee3cceba7824eac758d78652a8fe80f71b0c12; seven-commit comparison.Developers get clearer nonpaid author instructions, descriptive method contracts and narrower contribution checks. The separate KV freeze and new hardware campaign retain their own execution/acceptance boundaries.
2. Five material changes
tools/skill_eval_pr.pyto lead PLANNED feedback with next action, blocker and required evidence. Canonical/index changes can get an actual ancestor-bound source pin for the existing index check; plan and publisher use matching full history. #291 adds CLI stage/capture/report controls.tools/kv_live_authorization.jsonand existing admission/policy tools.applicability/recommendationsfor 17 methods under the accepted field semantics. All 20 registered methods now have applicability metadata; canonical sidecars feed generated catalog/coverage.tools/check_pr_references.pyto detect closing syntax embedded in PR-body sentences, including negation. #298 adds exactgpt-6.1-terraatxhigh/maxto.github/knowledge-model-policy.json.3. Architecture delta
The layer split is unchanged. Changes sit in Entry/Knowledge sidecars, the existing PR planning/feedback surface and external contribution checks; KV execution still belongs to the existing bounded controller. Reference/SearchSpace remain authoritative. A PLANNED summary is work instruction; it neither runs its suggested command nor changes the grader.
Proposed: #295 Async Workbench discusses manager/worker contexts and recovery. It is a draft with no assignee or delivered scheduler; #249/#268's existing ownership/review remains separate.
Documentation drift retained: the daily-admission guide still describes an unchanged checked-in schema-1 rollout. The generic architecture future-planning line concerns the engine/campaign lane; PR planning already exists. These historical descriptions must not override current configuration/focused contracts.
4. In-flight work and existing ownership
5. Evidence and limitations
This session inspected pinned source, actual merge flags, complete Status comments, relevant issue/PR discussions and owner decisions, and locally rendered the pinned SVG. Software/CI claims are attributed to their linked authors/reviewers; they were not rerun here. #291's controls are synthetic in-process CLI checks, not actual local-agent or sandbox qualification.
The workflow-specific manual-run query was unavailable; a sample of 30 recent repository runs is incomplete. No absence-of-execution, current ledger balance, billing settlement or second-pair effect is inferred from that sample or the missing outcome comment. The published v2 window remains historical.
No tests, model/provider/evaluation clients, GPU runs, workflow dispatch or repository-setting changes were performed for this update.
6. Next decisions
Dong1017 commentedon Nov 2, 2026
In-week developer update — 2026-11-02
1. Snapshot
Observed catch-up: the previous publication, 2026-11-01 19:13:56 → 2026-11-02 19:28:08 Asia/Shanghai. This consolidates the actual check rather than reconstructing daily observations; the weekly body remains unchanged.
6810870046b4f493d39b6eaede0f1a4004369235.67ee3cceba7824eac758d78652a8fe80f71b0c12.2baebf6ebb815ebf07d21c41e3b3754858c0798e; 11-commit comparison.Developer consequence: an actual downloadable preview now exists, operating knowledge has a clean accepted delivery, and H3 evidence distinguishes a bounded historical lossy result from still-unaccepted lossless/four-track goals.
2. Five material changes
.github/workflows/release.ymlandtools/check_release.py. The scheduled run succeeded; v0.1.0 Developer Preview was published November 2, 05:35:13 Shanghai, with wheel, sdist, standalone Codex ZIP and SHA256SUMS.6c9f90daae2d404915378b910f581b4dcff7e7da; that release is not the current main snapshot. The run started at 05:29 after the nominal 02:00 slot. #238 still awaits requester acceptance; actual account import and future timeliness are unverified. GPT-generated notes remain the open #313 extension.evidence/h3-ref2va-ascend-293/. Its frozen report records 407.269→108.120 s warm complete-HTTP latency, 73.45% lower, with 3.10% higher sampled peak HBM.a0677a03, reports only 1.57% from one four-logical-910C screening pair, below its 50% target; overall INCONCLUSIVE, failed lossy profiles and incomplete final confirmation remain.frameworks/pytorch/pytorch/andframeworks/torch-npu/torch-npu/, plus registry/catalog/package integration. It follows the explicit oversized-delivery revert #311.tools/skill_eval_local.pyandskill_eval_compare.py: new unparsed author logs retaincommands: null; legacy author-reported entries with unknown completed turns render an unknown observed command count.tool_callsfield is not an authenticated count of all model tools. #253's broader effectiveness/author-evidence acceptance remains open..github/labels.json, status/priority conventions, template labels and read-onlytools/check_labels.pyin the existing nightly lane. The existing contributor's receipt records live label reconciliation.status:proposedmeans a named pending decision. Drift reporting does not auto-fix labels; label maintenance must not manipulate the protected paid-execution switch. No labels/settings were changed by this reporting session.3. Architecture delta
The maintained layer split remains. New operating graphs enter through canonical knowledge/Reader; release tooling consumes packaged runtime/resources outside the experiment loop. H3 engine changes remain downstream contributions; retained campaign evidence does not add an InferRSI execution backend. Reference/SearchSpace remain authoritative. Proposed GPT notes and broader coordination work are separate from implemented publication and read-only checks.
Configuration/documentation drift: release-note categories and the release guide still name legacy
enhancement/bug/documentation, while the current label manifest uses prefixed names. The catch-all category remains present. Categorization needs reconciliation through existing owners; missing notes or publication failure are not inferred.4. In-flight work and existing ownership
5. Evidence and limitations
This session inspected pinned source, full edition/comments, merge flags, specific acceptance/decision receipts, release/tag/asset metadata and the scheduled run record. The pinned SVG was rendered locally. Package binaries were not downloaded, installed or imported; API digests are metadata, not a new independent archive validation.
H3 measurements/quality checks and software test results are carried from their exact author/reviewer records. Original media, weights and host logs remain external; no device replay or semantic-quality review was performed here. #317 is a moving draft, and its historical execution revisions are distinct from its publication head. A green CI job, accepted knowledge packaging or a published Release cannot establish campaign acceptance.
No tests, provider/model/evaluation clients, GPU/NPU experiments, workflow dispatch, credentials or repository-setting changes were performed for this report.
6. Next decisions