Add ga to python apidocs - #42
Merged
Merged
Conversation



### Description
It missed a space there.

### Motivation and Context
Right now the pipeline is failing because GSL was just converted from a
submodule to a cmake external project.
### Description
Delete CUB

### Motivation and Context
Because it is already in CUDA SDK.

The oneDNN 2.7.1 release includes multiple functional and performance
improvements.

Signed-off-by: George Nash <george.nash@intel.com>

### Description
Update the oneDNN library from 2.7.0 to 2.7.1. This contains multiple
functional and performance improvements.


### Motivation and Context
This is a minor point release from the oneDNN library that gives
performance and functional fixes that were found in the oneDNN 2.7
library shortly after release.

Signed-off-by: George Nash <george.nash@intel.com>

**Description**: Subgraph-level recompute This PR adds an optional capability trading additional re-computation for better memory efficiency. Specifically, a pre-defined operator list used to iterate the Graph to find some subgraphs for recompute, to reduce some stashed activations whose lifetime across forward and backward pass. When training with ORTModule, by default, the graph transformer will scan the execution graph to find all eligible subgraph to recompute, along with sizes that can save. An example looks like below. If we want to enable some of them to recompute, we can define env variable this way: `export ORTMODULE_ENABLE_MEMORY_ALLEVIATION="Mul+FusedMatMul+Cast+Unsqueeze+Unsqueeze+Cast+Sub+Mul+Add+BiasSoftmaxDropout+Cast+:1:-1,BiasGelu+:1:-1,BitmaskDropout+Cast+:1:-1,FusedMatMul+:1:-1,Cast+:1:-1,Mul+Add+:1:-1,Mul+Sub+:1:-1"` ``` [1,0]<stderr>:2,022-10-12 14:47:39.302,954,530 [W:onnxruntime:, memory_alleviation.cc:595 PrintSummary] [1,0]<stderr>:MemoryAlleviation Summary: [1,0]<stderr>: User config: [1,0]<stderr>: Mul+FusedMatMul+Cast+Unsqueeze+Unsqueeze+Cast+Sub+Mul+Add+BiasSoftmaxDropout+Cast+:1,BiasGelu+:1,BitmaskDropout+Cast+:1,FusedMatMul+:1,Cast+:1,Mul+Add+:1,Mul+Sub+:1 [1,0]<stderr>: ================================= [1,0]<stderr>: Subgraph: BitmaskDropout+ [1,0]<stderr>: AlleviationType: Disabled [1,0]<stderr>: Patterns: [1,0]<stderr>: PatternShape:input_ids_dim0 x 1,024 x Frequency:1 [1,0]<stderr>: -------------------------------- [1,0]<stderr>: Subgraph: BiasGelu+ [1,0]<stderr>: AlleviationType: Recompute [1,0]<stderr>: Patterns: [1,0]<stderr>: PatternShape:input_ids_dim0 x input_ids_dim1 x 4,096 x Frequency:24 [1,0]<stderr>: -------------------------------- [1,0]<stderr>: Subgraph: Reshape[1,0]<stderr>:+ [1,0]<stderr>: AlleviationType: Disabled [1,0]<stderr>: Patterns: [1,0]<stderr>: PatternShape:labels_dim0 x Frequency:1 [1,0]<stderr>: -------------------------------- [1,0]<stderr>: Subgraph: Unsqueeze+Unsqueeze+Cast+Sub+Mul+Mul+FusedMatMul+Cast+Add+BiasSoftmaxDropout+Cast+ [1,0]<stderr>: AlleviationType: Disabled [1,0]<stderr>: Patterns: [1,0]<stderr>: PatternShape:input_ids_dim0 x 16 x input_ids_dim1 x input_ids_dim1 x Frequency:23 [1,0]<stderr>: -------------------------------- [1,0]<stderr>: Subgraph: Mul+FusedMatMul+Cast+Unsqueeze+Unsqueeze+Cast+Sub+Mul+Add+BiasSoftmaxDropout+Cast+ [1,0]<stderr>: AlleviationType: Recompute [1,0]<stderr>: Patterns: [1,0]<stderr>: PatternShape:input_ids_dim0 x 16 x input_ids_dim1 x input_ids_dim1 x Frequency:1 [1,0]<stderr>: -------------------------------- [1,0]<stderr>: Subgraph: Mul+Add+ [1,0]<stderr>: AlleviationType: Recompute [1,0]<stderr>: Patterns: [1,0]<stderr>: PatternShape:input_ids_dim0 x 16 x input_ids_dim1 x 1 x Frequency:24 [1,0]<stderr>: -------------------------------- [1,0]<stderr>: Subgraph: FusedMatMul+Cast+Add+Reshape+Cast+ [1,0]<stderr>: AlleviationType: Disabled [1,0]<stderr>: Patterns: [1,0]<stderr>: PatternShape:input_ids_dim0 x 16 x input_ids_dim1 x 2 x 4 x Frequency:24 [1,0]<stderr>: -------------------------------- [1,0]<stderr>: Subgraph: Mul+Sub+ [1,0]<stderr>: AlleviationType: Recompute [1,0]<stderr>: Patterns: [1,0]<stderr>: PatternShape:input_ids_dim0 x 16 x input_ids_dim1 x 1 x Frequency:24 [1,0]<stderr>: -------------------------------- [1,0]<stderr>: Subgraph: Cast+ [1,0]<stderr>: AlleviationType: Recompute [1,0]<stderr>: Patterns: [1,0]<stderr>: PatternShape:1,024 x 1,024 x Frequency:97 [1,0]<stderr>: PatternShape:3 x 1,024 x Frequency:1 [1,0]<stderr>: PatternShape:8 x 64 x Frequency:24 [1,0]<stderr>: PatternShape:1,024 x 4,096 x Frequency:24 [1,0]<stderr>: PatternShape:4,096 x Frequency:24 [1,0]<stderr>: PatternShape:4,096 x 1,024 x Frequency:24 [1,0]<stderr>: -------------------------------- [1,0]<stderr>: Subgraph: FusedMatMul+ [1,0]<stderr>: AlleviationType: Recompute [1,0]<stderr>: Patterns: [1,0]<stderr>: PatternShape:input_ids_dim0 x input_ids_dim1 x 4,096 x Frequency:24 [1,0]<stderr>: -------------------------------- [1,0]<stderr>: ================================= ``` "Type config:" whether recompute is enabled by users. 0 - disable, 1- enable. "Subgraph" means what kind of subgraph will be recomputed, in this case, it is a single node "Gelu", and it will be "Recompute". "Shape && Frequency" means, for this recompute, one tensor of size (batch size, 500) will be saved because it will be recomputed. **Baseline** On a 1P model (DEBERTA V2), sequence length 256, training with 16 A100 GPUs. With latest main branch, we can run batch size 16, and the maximum batch size < 32. So 16 is usually chosen by data scientists. 65% of 40GB memory is used during training. The SamplesPerSec=479.2543353561354.  **With this PR** Gelu is recomputed for saving memory peak, batch size 32 can be run. The 97% of 40GB A100 is used, the SamplesPerSec=562.041593991271 (**1.17X** of baseline). 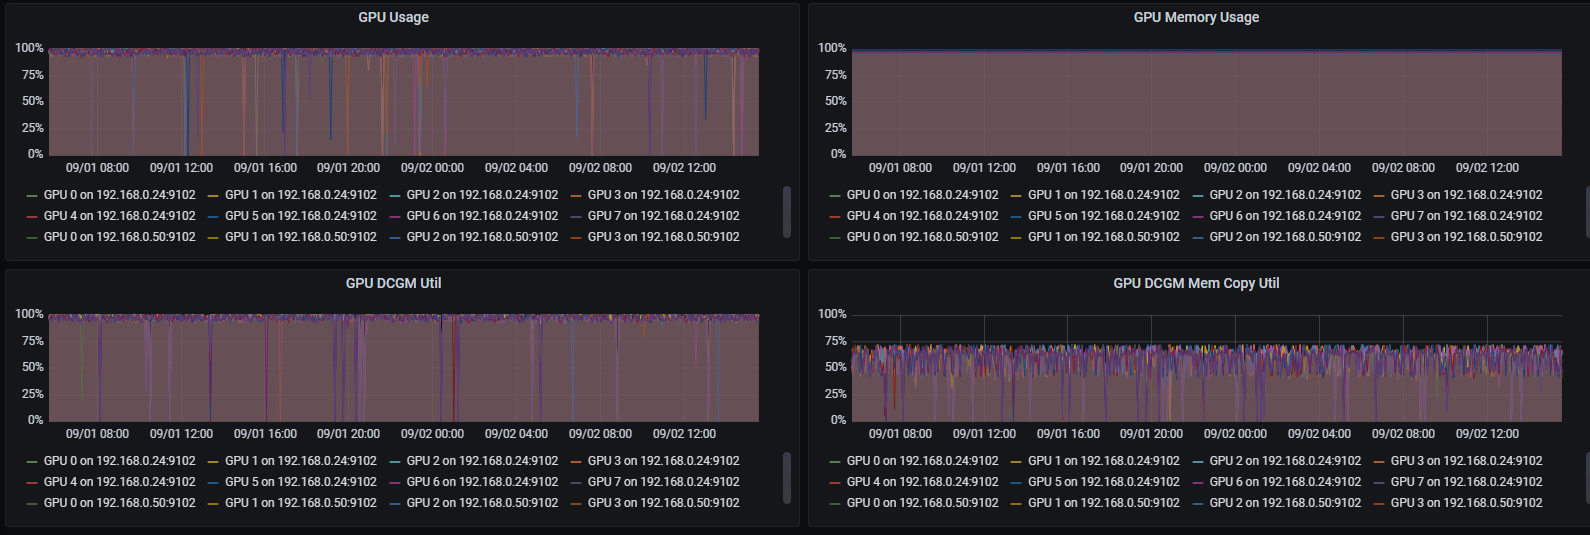 **Motivation and Context** - Why is this change required? What problem does it solve? - If it fixes an open issue, please link to the issue here.

### Description
<!-- Describe your changes. -->


### Motivation and Context
these workflows are prone to timeout.

1. Update CK to its latest develop branch
2. `-mllvm -amdgpu-early-inline-all=true` is critical to CK's
performance, ensure it is properly configured.
- The flags are propagated from target `hip-lang::device`'s
`INTERFACE_COMPILE_OPTIONS`, we must not manually add the flags.
- Instead, we must ensure this target is properly configured by checking
_CMAKE_HIP_DEVICE_RUNTIME_TARGET is set.

TL,DR

`hip-lang::device` sometime will be not be properly configured if our
`CMAKE_PREFIX_PATH` is not configured carefully. In the CI docker, the
configuration is in good state, but on dev machine it is not, which then
silently result poor performance for kernels. We fixed it in this PR and
add a guard to avoid unsuccessful future editing and to prevent
convoluted debugging process.

`_CMAKE_HIP_DEVICE_RUNTIME_TARGET ` is shared in
`/opt/rocm/lib/cmake/hip-lang/hip-lang-config.cmake` and it is internal
to
[CMake](https://gitlab.kitware.com/cmake/cmake/-/merge_requests/6121/diffs),
the variable name will not be changed in the foreseeable future.


### Description
<!-- Describe your changes. -->


### Motivation and Context
<!-- - Why is this change required? What problem does it solve?
- If it fixes an open issue, please link to the issue here. -->

Customer reported this issue: they see many warnings when doing hte evaluation using ORTModule.  After investigation, we found the `training_mode` is exported to a wrong value in evaluation mode, it's value should be 0, but we found it is 1. Fix: fix pythonop training mode if training_mode's type is torch._C._onnx.TrainingMode, then not matter it is EVAL or TRAINING, "if training_mode" will always be true
### Description
The failed tests are:
```
 [  FAILED  ] ModelTests/ModelTest.Run/cpu__models_zoo_opset7_ResNet101_DUC_HDC_ResNet101DUC7, where GetParam() = L"cpu_..\\models\\zoo\\opset7\\ResNet101_DUC_HDC\\ResNet101-DUC-7.onnx"
[  FAILED  ] ModelTests/ModelTest.Run/cpu__models_zoo_opset12_ResNet101_DUC_HDC12_ResNet101DUC12, where GetParam() = L"cpu_..\\models\\zoo\\opset12\\ResNet101_DUC_HDC-12\\ResNet101-DUC-12.onnx"
[  FAILED  ] ModelTests/ModelTest.Run/cpu__models_zoo_opset11_FCN_ResNet101_model, where GetParam() = L"cpu_..\\models\\zoo\\opset11\\FCN ResNet-101\\model.onnx"
[  FAILED  ] ModelTests/ModelTest.Run/cpu__models_zoo_opset10_SSD_model, where GetParam() = L"cpu_..\\models\\zoo\\opset10\\SSD\\model.onnx"

```
They are instable. Sometimes they fail with error "Message: bad
allocation".

Sample job:
https://dev.azure.com/onnxruntime/onnxruntime/_build/results?buildId=797861&view=logs&j=cceb3ef3-4a22-5fef-c5e9-ef6abe6579ed&t=fa89271b-d780-55e6-8822-71317e62ce21
### Add guidelines for ORTModule

As title.

Feel free to let me know if I missed something.

### Motivation and Context
<!-- - Why is this change required? What problem does it solve?
- If it fixes an open issue, please link to the issue here. -->
### Description
 This adds bfloat16 support to the oneDNN ep.

When using the oneDNN ep this enables bfloat16 support for the following
ops:

Exp, Sigmoid, Tanh, Relu, MatMul, Gelu, BiasGelu, Add, Sub,
Mul, Div, Div, Sqrt, Pow, ReduceMean,  Abs, Cast, Equal, Exp,
FastGelu, FusedMatMul, Gemm, Greter, GreaterOrEqual, LeakyRelu,
Less, LessOrEqual, LRN, ReduceOps, Reshape, Squeeze, Transpose,
 and Unsqueeze.

LayerNorm with some internal casting.
BatchNorm only enabled BFloat16 for input and output, scale and bias
still need fp32 input.

Added bfloat16 unit tests for all of the operators in question. When
possible we reused the already existing unit tests that were added by
CUDA and ROCM eps.

In many of the unit tests an unusual pattern will be seen

    #if defined(USE_DNNL)
    TEST(Test, bfloat16_test) {
      #if defined(USE_DNNL)
        // oneDNN ep specific code
      #endif
       //test code
    }
    #endif

Although it looks unusual this was purposely done if another ep
implements bfloat16 support for that operator they will be able to
enable the unit test by adding there execution provider to the first
line without needing to edit inside the test.

Example: `#if defined(USE_CUDA) || defined(USE_DNNL)` see the
MatMul_float16 test in matmul_test.cc for and example of how this is
useful.

Additionally two new ISA checks (AVX512_BF16 and AMX-BF16) were added to
the cpuid_info code in. This was important to detecting is bfloat16
operations are supported by the CPU.

### Motivation and Context
This expands the capabilities of the oneDNN execution provider to
support models containing bfloat16 operations.

Signed-off-by: George Nash <george.nash@intel.com>
Signed-off-by: Ruihan-Yin <ruihan.yin@intel.com>

### Description
* Add getter/setter to access and update C# OrtEnv log level
* Add C API about updating ort env with custom log level to support the
setter above (Following [pybind
implementation](https://github.com/microsoft/onnxruntime/blob/952c99304a764328070ac6c07f510deec06dedf4/onnxruntime/python/onnxruntime_pybind_state.cc#L923-L924))
* Add test case to verify getter & setter


### Motivation and Context
* For C++/Python, the log level can be adjusted via OrtEnv, and this
feature is missing in C# binding
### Description
Upgrade cmake version to 3.24 because I need to use a new feature that
is only provided in that version and later. Starting from cmake 3.24,
the
[FetchContent](https://cmake.org/cmake/help/latest/module/FetchContent.html#module:FetchContent)
module and the
[find_package()](https://cmake.org/cmake/help/latest/command/find_package.html#command:find_package)
command now support integration capabilities, which means calls to
"FetchContent" can be implicitly redirected to "find_package", and vice
versa. Users can use a cmake variable to control the behavior. So, we
don't need to provide such a build option. We can delete our
"onnxruntime_PREFER_SYSTEM_LIB" build option and let cmake handle it.
And it would be easier for who wants to use vcpkg.


### Motivation and Context

Provide a unified package management method, and get aligned with the
community. This change is split from microsoft#13523 for easier review.
### Description

The yum repo is called: ["Extra Packages for Enterprise Linux
(EPEL)"](https://docs.fedoraproject.org/en-US/epel/#what_is_extra_packages_for_enterprise_linux_or_epel)
. It is provided by Fedora community for RHEL/CentOS/... Linux distros.
However, we do not really need it.

### Motivation and Context

To minimize the number of dependencies. And the command "yum install -y
https://dl.fedoraproject.org/pub/epel/epel-release-latest-7.noarch.rpm"
often fails because the website is often not responding,
1. Remove the cmake option onnxruntime_DEV_MODE and replace it with
"--compile-no-warning-as-error"
2. Suppress some GSL warnings because now we treat nvcc diag warnings as
errors

### Description
In the TVM EP, this adds more entries to the conversion from
`ONNXTensorElementDataType` to `DLDataType`. Additionally, it removes an
unused function and updates the TVM revision to allow running models
from recent revisions of TVM.

### Motivation and Context
In the TVM EP, the mapping from `ONNXTensorElementDataType` to
`DLDataType` was incomplete and neglected several integer types (in
particular `ONNX_TENSOR_ELEMENT_DATA_TYPE_UINT8` and
`ONNX_TENSOR_ELEMENT_DATA_TYPE_INT8`) which prevented some models from
running.

Co-authored-by: Peter Salas <psalas@octoml.ai>
microsoft#13393)

The old runtime optimization format is not readily convertible to the new one without extra information for translating kernel def hashes.
Ignore such saved runtime optimizations and output a warning for now.
Pytorch was added to inference pipelines in PR microsoft#8027. But, actually
these pipelines do not use PyTorch. PyTorch is huge, here we need to
install it for 4 different Python versions. If we remove PyTorch, we
will significantly reduce the image size. And, now downloading a pytorch
package often takes more than 1 hour. If we do it 4 times, it may take 4
hours.

Valgrind was added by me long time back, and it was not used too. Now we
run Linux tests outside of docker containers. So, when we have the need,
we could install it through apt-get on Ubuntu instead of doing it in the
CentOS container.

### Description
Properly cleans up all temporary resources created while running
benchmarks.

Details:
- Dump all temporary artifacts (TRT engines, TRT profiles, inference
profiles, fp16 models) into a temp directory in `/tmp/`. Each model/EP
combination has its own temp directory that is deleted after validation
and benchmarking.
- Allow running both validation and benchmarking in one invocation of
the benchmark.py script. This is necessary to allow the benchmarking
step to reuse artifacts (e.g., TRT engines) created during validation.
Before this PR, we ran validation on all model/EP combinations before
running benchmarks on all combinations again. This required us to keep
all temporary artifacts for all model/EP combinations throughout the
entire run (expensive).
- Create individual functions for validation and benchmarking (split-up
large function that did it all)

### Motivation and Context
The EP Perf pipeline failed to run because the script generated too much
output and the VM ran out of disk space.
…icrosoft#13587)

### Description
Fix microsoft#13509

### Motivation and Context
The exception was caused by the incorrect fetches, which was from the
binding with last test cases.

https://github.com/microsoft/onnxruntime/blob/efcbdac58e542273c7cd42f5e5bcd01c0218f0e3/onnxruntime/core/session/onnxruntime_c_api.cc#L809-L815

### Description
Add a DML registration for Shape to avoid copying back to the CPU just
to get the shape of a GPU tensor.


### Motivation and Context
When using free dimensions, many Transformers models extensively use the
`Shape` operator. This causes hundreds of GPU->CPU copy that should be
completely avoidable. Note that this change also uses the same
heuristics as other providers (e.g. CUDA) to force some tensors on the
CPU in certain situations.

Co-authored-by: Patrice Vignola <pavignol@microsoft.com>

### Description
Redo the round using gsl:narrow and SafeInt


### Motivation and Context
<!-- - Why is this change required? What problem does it solve?
- If it fixes an open issue, please link to the issue here. -->

On AMD Instinct MI200 GPUs, the FP16 and BF16 V_DOT2 and MFMA matrix
instructions flush input and output denormal values to zero. When
training using FP16 precision, some models may fail to converge with
FP16 denorms flushed to zero. The affected instructions are only used by
rocBLAS (GEMM) and MIOpen (convolution) kernels; all other onnxruntime
operations will not encounter this behavior. All other supported AMD
GPUs will not encounter this behavior.

rocBLAS and MIOpen provide alternate implementations for affected FP16
operations. Alternate implementations for BF16 operations are not
provided; BF16 numbers have a larger dynamic range than FP16 numbers and
are less likely to encounter denormal values. For the FP16 alternate
implementations, FP16 input values are cast to an intermediate BF16
value and then cast back to FP16 output after the accumulate FP32
operations. In this way, the input and output types are unchanged.

Denormal values more frequently occur in the backward pass of training
during gradient calculation. Therefore, it is necessary to track when
the backward pass of training is executing. For the ROCm EP only, the
`__backwardpass` attribute is added to all Nodes after the YieldOp is
detected. This takes place in a level1 graph optimization pass. The
attribute is forwarded to any newly created FusedMatMul Nodes. In
addition, the scope-based helper class `BackwardPassGuard` is provided
to toggle state for rocblas. This behavior of using the alternate
implementations during the backward pass is made automatic with this PR.
This default behavior can be overridden using environment variables,
ROCBLAS_INTERNAL_FP16_ALT_IMPL and
MIOPEN_DEBUG_CONVOLUTION_ATTRIB_FP16_ALT_IMPL. The behavior of these
environment variables is as follows:

|              | forward   | backward  |
|--------------|-----------|-----------|
| Env unset    | original  | alternate |
| Env set to 1 | alternate | alternate |
| Env set to 0 | original  | original  |

See also:


https://pytorch.org/docs/stable/notes/numerical_accuracy.html#reduced-precision-fp16-and-bf16-gemms-and-convolutions-on-amd-instinct-mi200-devices


### Description
<!-- Describe your changes. -->
Introduce Gemm weights pre-pack.

### Motivation and Context
A 1-P customer requested a performance improvement for DeepGru which
consumes a bulk of CPU in their model. This provides measurable
performance improvements.

Customer model numbers.

gru: mean = 356 us; 1ms = 99.8 prctile; 99th prctile = 665 ms
(yuslepukhin/deep_gru_opt)
main: mean = 375 us; 1ms = 99.8 prctile; 99th prctile = 695 ms (where
yuslepukhin/deep_gru_opt branched off main)
1.13.1: mean = 391 us; 1ms = 99.6 prctile; 99th prctile = 744 ms
### Description
<!-- Describe your changes. -->


### Motivation and Context
<!-- - Why is this change required? What problem does it solve?
- If it fixes an open issue, please link to the issue here. -->
…icrosoft#13734)

### Description
Add mixed datatype support for DML's LayerNorm contrib op.


### Motivation and Context
The fusion logic removes casts around LayerNorm in the graph because the
contrib version of the op supports mixed datatypes. Scale, Bias and
Output's datatypes must match, but input's datatype can be different.
…lptr) (microsoft#13818)

### Description
Add support for LayerNorm scale == nullptr != bias == nullptr

### Description
This PR implements the **Concat Operator** for the **OneDNN Execution
Provider**.

### Motivation and Context
- As part of evaluating ORT performance on ARM based targets such as
Graviton3, we discovered that the OneDNN EP had some gaps on operator
coverage.
- The Concat Operator is fairly common and used in models such as
Yolov5, MobileNet, DistillBert and GPT2
- For Yolov5 specifically, this improves average inference time over 100
runs on Graviton3 from 180.2ms to 115.5ms when using OneDNN + ARM
Compute Library.

Co-authored-by: Gaz Iqbal <giqbal@octoml.ai>
### Description
Add the NonZero op for DML


### Motivation and Context
NonZero is used in a few transformer models, so having a DML
implementation will stop large tensors from being transferred to the CPU
and back to the GPU
### Description
GetInputMemoryType was introduced in ver 13 in [this
PR](microsoft#10879). The ver check
introduced in this PR allows custom ops compiled using older versions to
work with newer versions (> 12) of the ORT binary.

### Motivation and Context
Fixes binary compatibility.

### Description
fix a wrong assert condition in benchmark_helper.py (introduced in
microsoft#13455)


### Description
<!-- Describe your changes. -->

Testcases of LayerNorm with fp16/bf16 are failed in Andriod and IOS
since the two platforms don't support the combinations of datatypes as
well.


https://dev.azure.com/onnxruntime/onnxruntime/_build?definitionId=134&_a=summary

https://dev.azure.com/onnxruntime/onnxruntime/_build?definitionId=53&_a=summary

### Motivation and Context
<!-- - Why is this change required? What problem does it solve?
- If it fixes an open issue, please link to the issue here. -->

### Description
This PR enables building nuget packages locally for on device training
using --build_nuget arg.
This PR also enables the C# bindings by default in the managed package.
If a user triggers any training apis when the native binary is not built
for training, an exception with message "Training is disabled in the
current build. Please build ONNXRuntime from source with the build flags
enable_training and enable_training_on_device. " is thrown.

Build command for creating nuget packes for on device training:
build.bat --enable_training --enable_training_on_device --build_nuget

2 Nuget packages are built
1. Microsoft.ML.OnnxRuntime.Managed
2. Microsoft.ML.OnnxRuntime.Training OR
Microsoft.ML.OnnxRuntime.Training.Gpu


### Motivation and Context
<!-- - Why is this change required? What problem does it solve?
- If it fixes an open issue, please link to the issue here. -->
### Description
<!-- Describe your changes. -->


### Motivation and Context
<!-- - Why is this change required? What problem does it solve?
- If it fixes an open issue, please link to the issue here. -->
### Description
Use CCache and ADO CacheTask to Accelerate MacOS build.
ref:
https://learn.microsoft.com/en-us/azure/devops/pipelines/release/caching?view=azure-devops

### Motivation and Context
The MacOS CI duration could be reduced from more than **70minutes** to
**10 minutes**

https://dev.azure.com/onnxruntime/onnxruntime/_build/results?buildId=824912&view=results
Upgrade pybind11 to include the fix for microsoft#9735
…oft#13852)

Fix various flaky build error due to onnxruntime_session missing dependencies on hipify generated files.
### Description

Add SkipLayerNormalization for the DML EP
### Description

### Motivation and Context
Test data in the image has been fixed.
microsoft#13874)

This reverts commit 87d5703.

### Motivation and Context
There was a bug in Linux CUDA installation.
The OS image is updated.
The TestCUDAProviderOptions could be reenabled.
### Description
Decouple strided tensor support from ENABLE_TRAINING

### Motivation and Context
This is step 1 for creating a dedicated build for on device training.
Intention is

1. We can set ENABLE_STRIDED_TENSORS in cmake when either
ENABLE_TRAINING or ENABLE_TRAINING_ON_DEVICE is selected, this way we
dont have to use if defined(ENABLE_TRAINING) ||
defined(ENABLE_TRAINING_ON_DEVICE ) everywhere in the code.

2. This also paves the way to easily enable strided tensor support for
inference in future (if required).

### Description
Exposing get and set Learning rate for optimizer


### Motivation and Context
you can now set learning rate for optimizer.

Bumps [minimatch](https://github.com/isaacs/minimatch) from 3.0.4 to 3.0.5. <details> <summary>Commits</summary> <ul> <li><a href="https://github.com/isaacs/minimatch/commit/707e1b231d5ddf5b00040bd04968a1a092992d1a"><code>707e1b2</code></a> 3.0.5</li> <li><a href="https://github.com/isaacs/minimatch/commit/a8763f4388e51956be62dc6025cec1126beeb5e6"><code>a8763f4</code></a> Improve redos protection, add many tests</li> <li><a href="https://github.com/isaacs/minimatch/commit/bafa295617d984c5863b13a33b2bb601c67e4a8b"><code>bafa295</code></a> Use master branch for travis badge</li> <li><a href="https://github.com/isaacs/minimatch/commit/013d64dc242213bab1cf090d4a9e6bdf02f61160"><code>013d64d</code></a> update travis</li> <li>See full diff in <a href="https://github.com/isaacs/minimatch/compare/v3.0.4...v3.0.5">compare view</a></li> </ul> </details> <br /> [](https://docs.github.com/en/github/managing-security-vulnerabilities/about-dependabot-security-updates#about-compatibility-scores) Dependabot will resolve any conflicts with this PR as long as you don't alter it yourself. You can also trigger a rebase manually by commenting `@dependabot rebase`. [//]: # (dependabot-automerge-start) [//]: # (dependabot-automerge-end) --- <details> <summary>Dependabot commands and options</summary> <br /> You can trigger Dependabot actions by commenting on this PR: - `@dependabot rebase` will rebase this PR - `@dependabot recreate` will recreate this PR, overwriting any edits that have been made to it - `@dependabot merge` will merge this PR after your CI passes on it - `@dependabot squash and merge` will squash and merge this PR after your CI passes on it - `@dependabot cancel merge` will cancel a previously requested merge and block automerging - `@dependabot reopen` will reopen this PR if it is closed - `@dependabot close` will close this PR and stop Dependabot recreating it. You can achieve the same result by closing it manually - `@dependabot ignore this major version` will close this PR and stop Dependabot creating any more for this major version (unless you reopen the PR or upgrade to it yourself) - `@dependabot ignore this minor version` will close this PR and stop Dependabot creating any more for this minor version (unless you reopen the PR or upgrade to it yourself) - `@dependabot ignore this dependency` will close this PR and stop Dependabot creating any more for this dependency (unless you reopen the PR or upgrade to it yourself) - `@dependabot use these labels` will set the current labels as the default for future PRs for this repo and language - `@dependabot use these reviewers` will set the current reviewers as the default for future PRs for this repo and language - `@dependabot use these assignees` will set the current assignees as the default for future PRs for this repo and language - `@dependabot use this milestone` will set the current milestone as the default for future PRs for this repo and language You can disable automated security fix PRs for this repo from the [Security Alerts page](https://github.com/microsoft/onnxruntime/network/alerts). </details> Signed-off-by: dependabot[bot] <support@github.com> Co-authored-by: dependabot[bot] <49699333+dependabot[bot]@users.noreply.github.com>

### Description
 fix session option setting of memory pattern.

### Description
- Use same data type as input for mask_index tensor which is used as DML
GEMM API's C parameter.
- Remove gsl header include as it is already gets included transitively.


### Motivation and Context
- Why is this change required? What problem does it solve?
Bug found in internal conformance testing.
- If it fixes an open issue, please link to the issue here.
N/A
Always build with XNNPACK EP in iOS CI build.
Combine builds for CPU, CoreML, and XNNPACK EPs due to limited build agent resources.

### Description
<!-- Describe your changes. -->

1. Remove ROCm5.3 pipeline because it has rocblas bug, we don't need it.
2. We removed the dependency on centos docker image provided by
AMD(https://hub.docker.com/r/rocm/dev-centos-7) and build ROCm centos
base image by ourselves. The reference
dockerfile(https://github.com/RadeonOpenCompute/ROCm-docker/blob/master/dev/Dockerfile-centos-7)
is very redundant for our need. We simplified the ROCm manylinux
dockerfile.
3. Different versions of rocm use the same dockerfile
`Dockerfile.manylinux2014_rocm`.

### Motivation and Context
<!-- - Why is this change required? What problem does it solve?
- If it fixes an open issue, please link to the issue here. -->

Co-authored-by: peixuanzuo <peixuanzuo@linmif39a000004.zvflicr54joexhdgnhvmxrxygg.phxx.internal.cloudapp.net>
…cSelection (microsoft#13758)

### Description
<!-- Describe your changes. -->

1. Update FastGelu conditions for supported parameters, avoid redundant
configurations participating in tuning。
2. Add kernel explorer test for FastGeluStaticSelection

### Motivation and Context
<!-- - Why is this change required? What problem does it solve?
- If it fixes an open issue, please link to the issue here. -->

Co-authored-by: peixuanzuo <peixuanzuo@linmif39a000004.zvflicr54joexhdgnhvmxrxygg.phxx.internal.cloudapp.net>
### Description
disable closure compiler in debug build. after this change, emscripten
will only run closure compiler in release build.





This file contains hidden or bidirectional Unicode text that may be interpreted or compiled differently than what appears below. To review, open the file in an editor that reveals hidden Unicode characters.
Learn more about bidirectional Unicode characters
Sign up for free
to join this conversation on GitHub.
Already have an account?
Sign in to comment
20 participants


Add this suggestion to a batch that can be applied as a single commit.This suggestion is invalid because no changes were made to the code.Suggestions cannot be applied while the pull request is closed.Suggestions cannot be applied while viewing a subset of changes.Only one suggestion per line can be applied in a batch.Add this suggestion to a batch that can be applied as a single commit.Applying suggestions on deleted lines is not supported.You must change the existing code in this line in order to create a valid suggestion.Outdated suggestions cannot be applied.This suggestion has been applied or marked resolved.Suggestions cannot be applied from pending reviews.Suggestions cannot be applied on multi-line comments.Suggestions cannot be applied while the pull request is queued to merge.Suggestion cannot be applied right now. Please check back later.
No description provided.